Meet Torus Foundry
Our complete AI infrastructure and energy management system. Preassembled in the USA, fast to commission, and designed to solve power constraints.
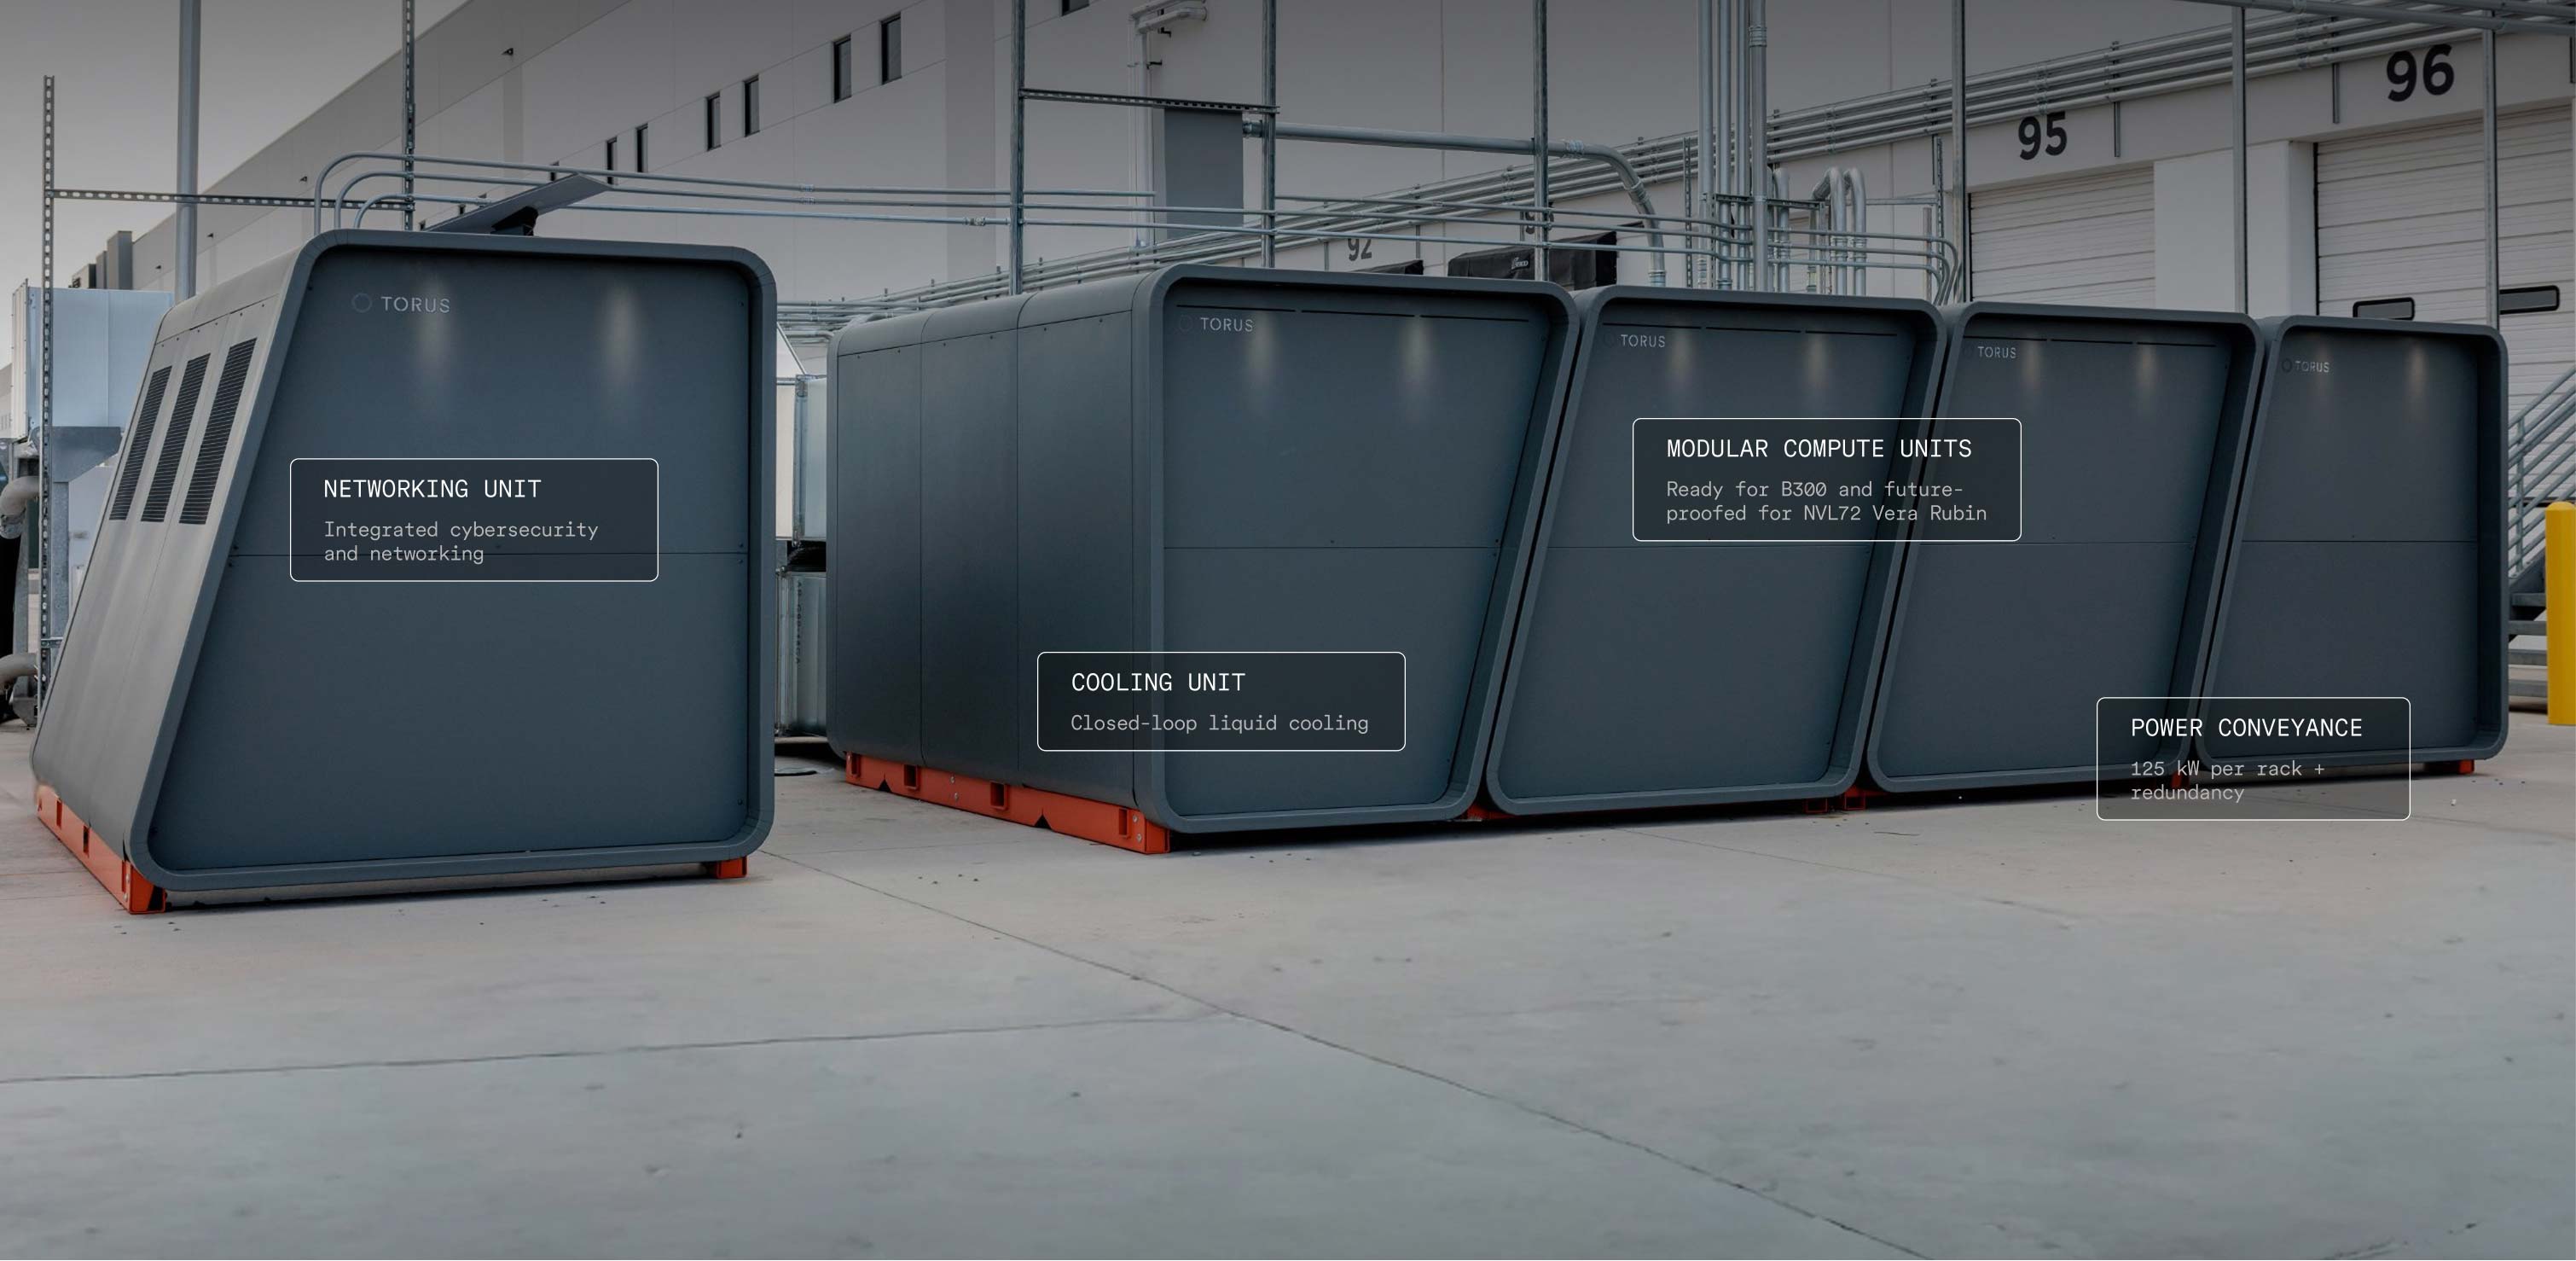
Turnkey unit
Includes GPUs, fiber, networking, cooling, power distribution, security, and monitoring.
Next-gen power per rack
Ready to power B300s and future-proofed to support NVL72 including Vera Rubin and other next-gen load requirements.
Energy storage & management
Integrated peak shaving and load shifting to free up capacity and improve grid resilience.
Single vendor
System design, permitting, installation, commissioning, and lifetime O&M from one trusted partner.
Foundry brings chips to power, not power to chips.
We deploy modular compute alongside energy storage on existing grid interconnections to power IT load with capacity that's available today.
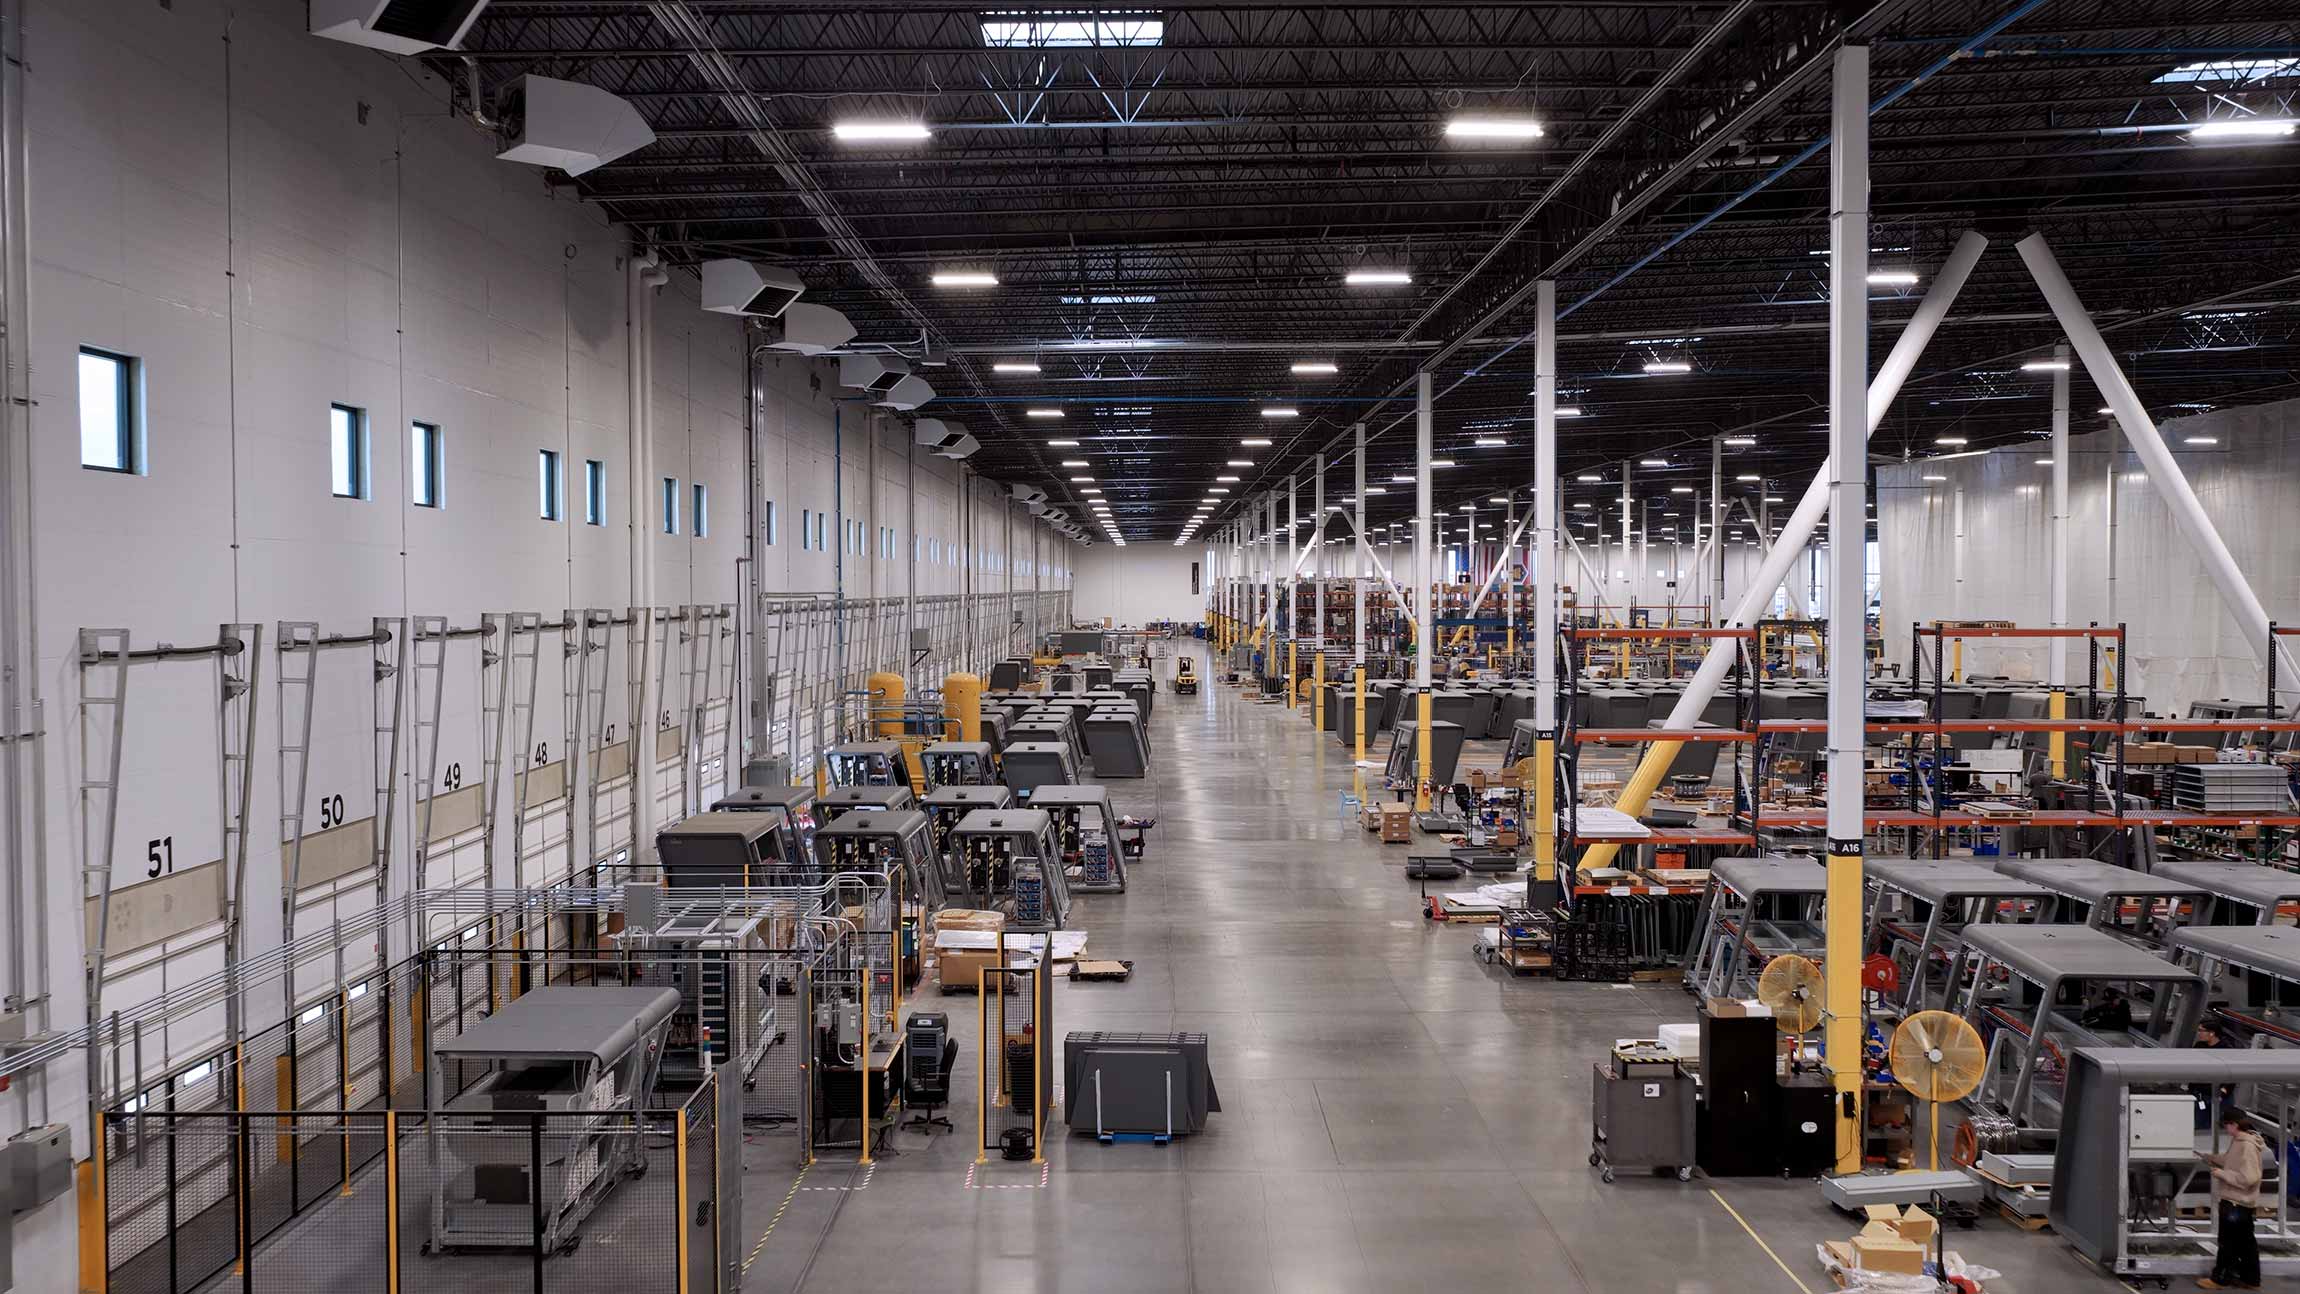
Prefabricated units built in the USA
Foundry is manufactured and assembled at GigaOne, our 545,000 sq. ft. production facility in Salt Lake City, UT. Each unit is pre-tested, arrives on-site fully assembled, and is installed and commissioned in 1-2 days.
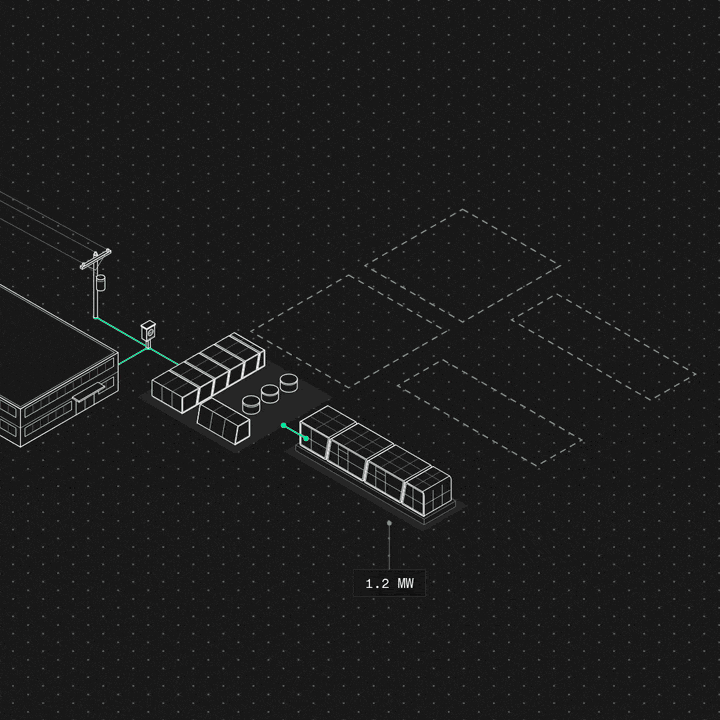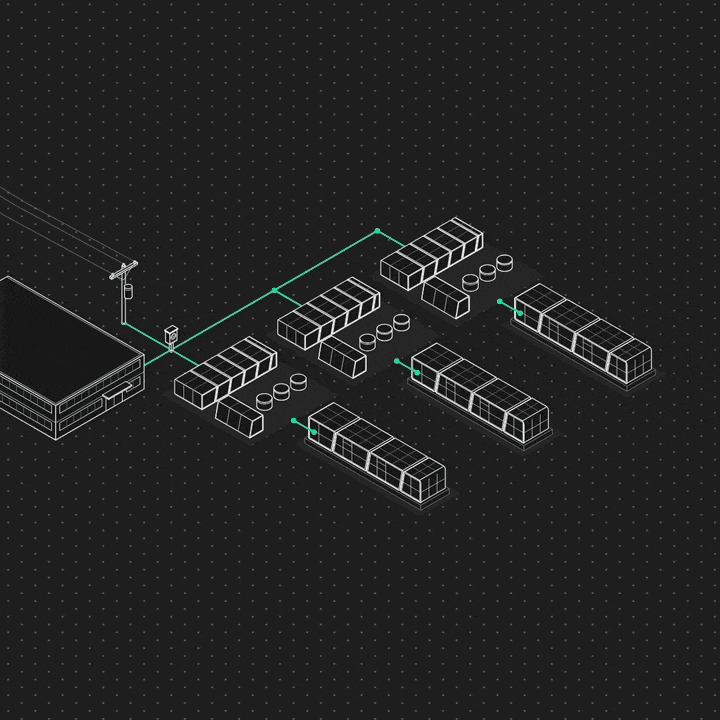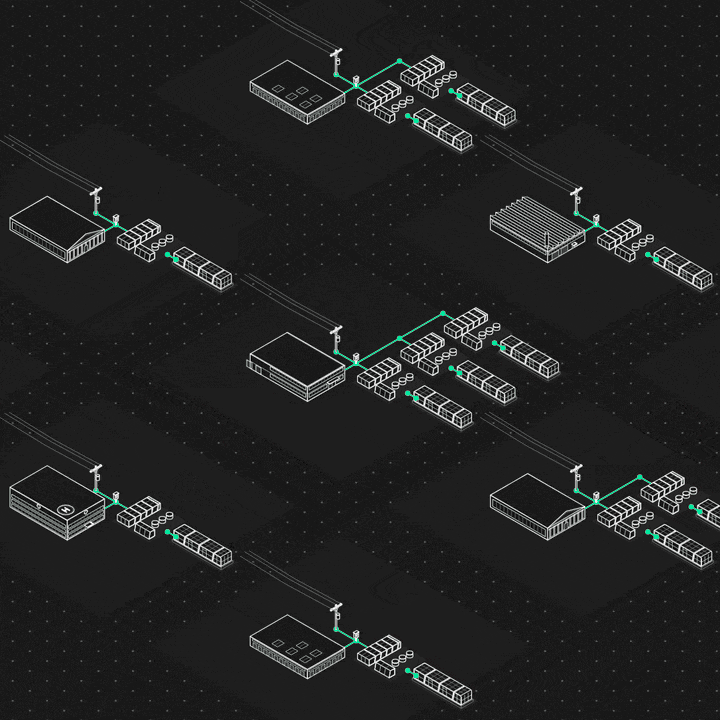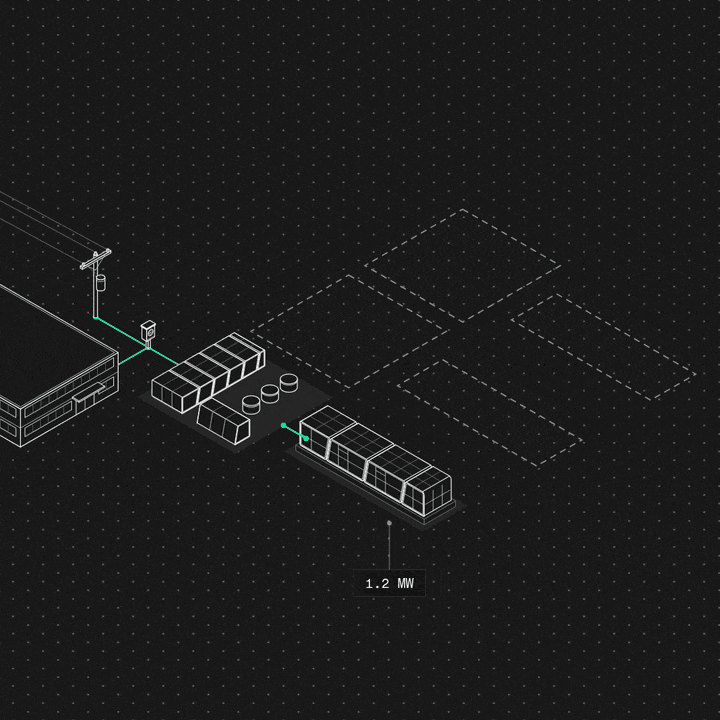
Scale at one site or across many
Foundry's modular design allows you to scale IT load in 1.2 MW increments, reducing the risk of overbuilding. Its small footprint is designed to install on already developed land, allowing compute to be easily distributed across multiple sites.
Who Foundry is for
- Neoclouds
Bring GPU capacity online without waiting years for a new grid connection. Foundry connects to existing capacity and pairs with hybrid energy storage, removing power as a constraint to your buildout.
- Enterprise businesses
Get dedicated GPU capacity hosted on-prem or at one of our sites. Single-tenant control means your data, models, and IP remain secure.
- Compute aggregators
Add supply to your marketplace without owning any infrastructure. Torus deploys the Foundry units and GPUs, and you rent that compute capacity to your customers.
- Telecom providers
Quickly transform existing sites into AI capacity. Foundry is modular and compact, allowing you to add GPU compute without building new campuses.
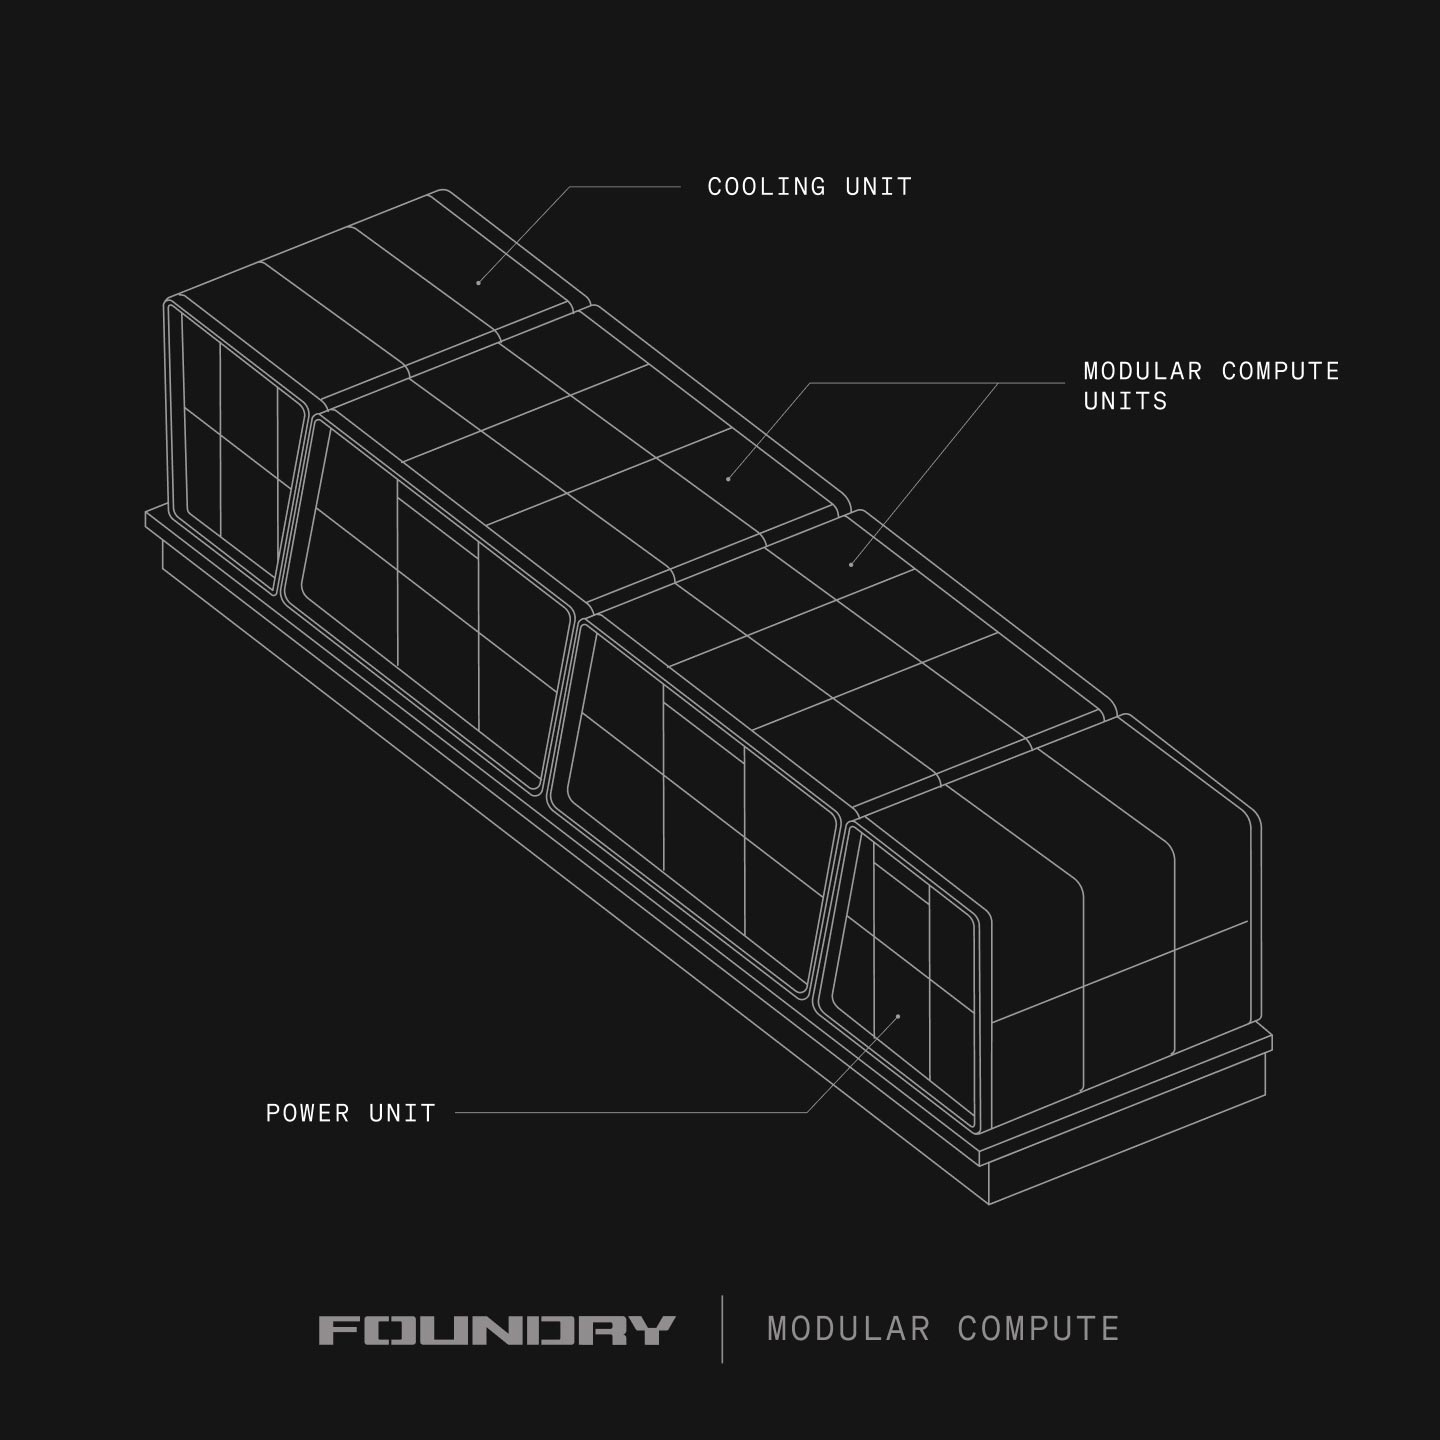
Engineered for GPU workloads
- Server rack load
125 kW
- Networking rack load
50 kW
- Total IT load
1,200 kW
- System footprint
577 sq ft
- Scale
Architected to add rack power as chip demand increases
- System cluster size
72 nodes
- HGX B300 GPUs per system
576 GPUs
- Racks per system
8 server racks, 4 networking racks
- System cooling ratio
80% liquid / 20% air
- Waterless by design
No on-site water connection required
- System cooling
Closed-circuit, direct-to-chip TCS loop
